DU Yiming
Email: ydu@se.cuhk.edu.hk

Huawei Hong Kong Research Institute
LegoX Team
Hong Kong, China
Hi, I am Yiming (Elvin) DU, a researcher at Huawei Hong Kong Research Institute, a member of the LegoX team, and a core contributor to LEGO-RL. My research focuses on coding agents, agentic reinforcement learning, and large language model agents. Recently, I have been working on long-horizon agent RL in real-world software engineering environments, harness-native training, and consistency between training and inference.
I received my Ph.D. from The Chinese University of Hong Kong, where I was supervised by Prof. Kam-Fai Wong in the Department of SEEM and the MoE Key Laboratory of High Confidence Software Technologies. From January to June 2025, I visited EdinburghNLP, working with Prof. Jeff Z. Pan. Previously, I interned at Huawei Noah’s Ark Lab and SenseTime Research, and conducted research at Imperial College London and City University of Hong Kong. I received my M.Eng. and B.Eng. in Computer Science from Southeast University.
My broader goal is to build agents that learn from interaction, retain useful experience, and reliably solve complex tasks over time. My work has appeared in venues including ICLR, AAAI, EMNLP, and ACM Computing Surveys.
Research Interests
-
Coding Agents & Agentic Reinforcement Learning. Long-horizon learning in real software engineering environments, harness-native training, and training–inference consistency. I study how to train reliable coding agents within the tools and execution workflows they use at deployment.
Representative works: LEGO-RL, SWE-Lego. -
Memory & Reasoning for LLM Agents. Long-term and multimodal memory, temporal reasoning, and retrieval over extended interactions, connecting my earlier work on personal assistants with agents that learn from experience.
Representative works: MEMORY-T1 (ICLR 2026), MemGuide (AAAI 2026), MemLens, Multimodal Retrieval Heads, PerLTQA (Best Paper, SIGHAN 2024), Rethinking Memory in AI. -
Data & Learning for Interactive Agents. High-quality trajectory and dialogue data, robust supervised fine-tuning, and personalized multi-turn interaction, spanning software engineering agents and conversational assistants.
Representative works: SWE-Lego, ReSURE (EMNLP 2025), Flexibly Utilize Memory (EMNLP 2025), Sticker Retrieval (AAAI 2025).
Featured Project
LEGO-RL: Harness-Native Reinforcement Learning for Coding Agents brings reinforcement learning to native coding-agent harnesses, with an emphasis on faithful optimization, reliable execution, and observable training.
Paper · GitHub · Hugging Face · Project / Docs
Honors & Awards
- 2024 — Overseas Research Attachment Programme (ORAP) Award, CUHK.
- 2024 — Best Paper Award, ACL-SIGHAN 2024 (for PerLTQA).
- 2020 — 1st Place, Jiangsu Postgraduate Mathematical Modeling Innovation Practice Competition.
- 2018 – 2020 — Excellent Scholarships: Shenzhen Stock Exchange, Southeast University, Huawei, Keyuan Automation.
- 2018 — 1st Place, Chinese Undergraduate Computer Design Contest; Meritorious Winner, Mathematical Contest in Modeling (MCM).
Academic Services
- Reviewer: ACL, EMNLP, IJCAI, Knowledge-Based Systems (KBS), etc.
- Patent: A dialogue memory storage, extraction and electronical device — Baojun Wang, Yiming Du, Kam-Fai Wong (Huawei, 2024).
news
| Sep 24, 2026 | I have received my Ph.D. from The Chinese University of Hong Kong, supervised by Prof. Kam-Fai Wong. I am now a researcher at Huawei Hong Kong Research Institute, a member of the LegoX team, and a core contributor to LEGO-RL. |
|---|---|
| Aug 18, 2026 | We introduce LEGO-RL: Harness-Native Reinforcement Learning for Coding Agents. Read the paper and explore the code, models, and documentation. |
| May 26, 2026 | New collaborative work: Can Retrieval Heads See Images? Multimodal Retrieval Heads in Long-Context Vision-Language Models. Read the paper. |
| May 14, 2026 | 📄 New paper MemLens: Benchmarking Multimodal Long-Term Memory in Large Vision-Language Models released on arXiv. |
| Jan 22, 2026 | 🎉 Our paper MEMORY-T1: Reinforcement Learning for Temporal Reasoning in Multi-Session Agents is accepted to ICLR 2026. |
| Jan 04, 2026 | Our paper SWE-Lego: Pushing the Limits of Supervised Fine-tuning for Software Issue Resolving is available on arXiv. We study supervised fine-tuning for software engineering agents. |
selected publications
- LEGO-RL: Harness-Native Reinforcement Learning for Coding AgentsarXiv preprint arXiv:2608.17393. Hugging Face , 2026
-
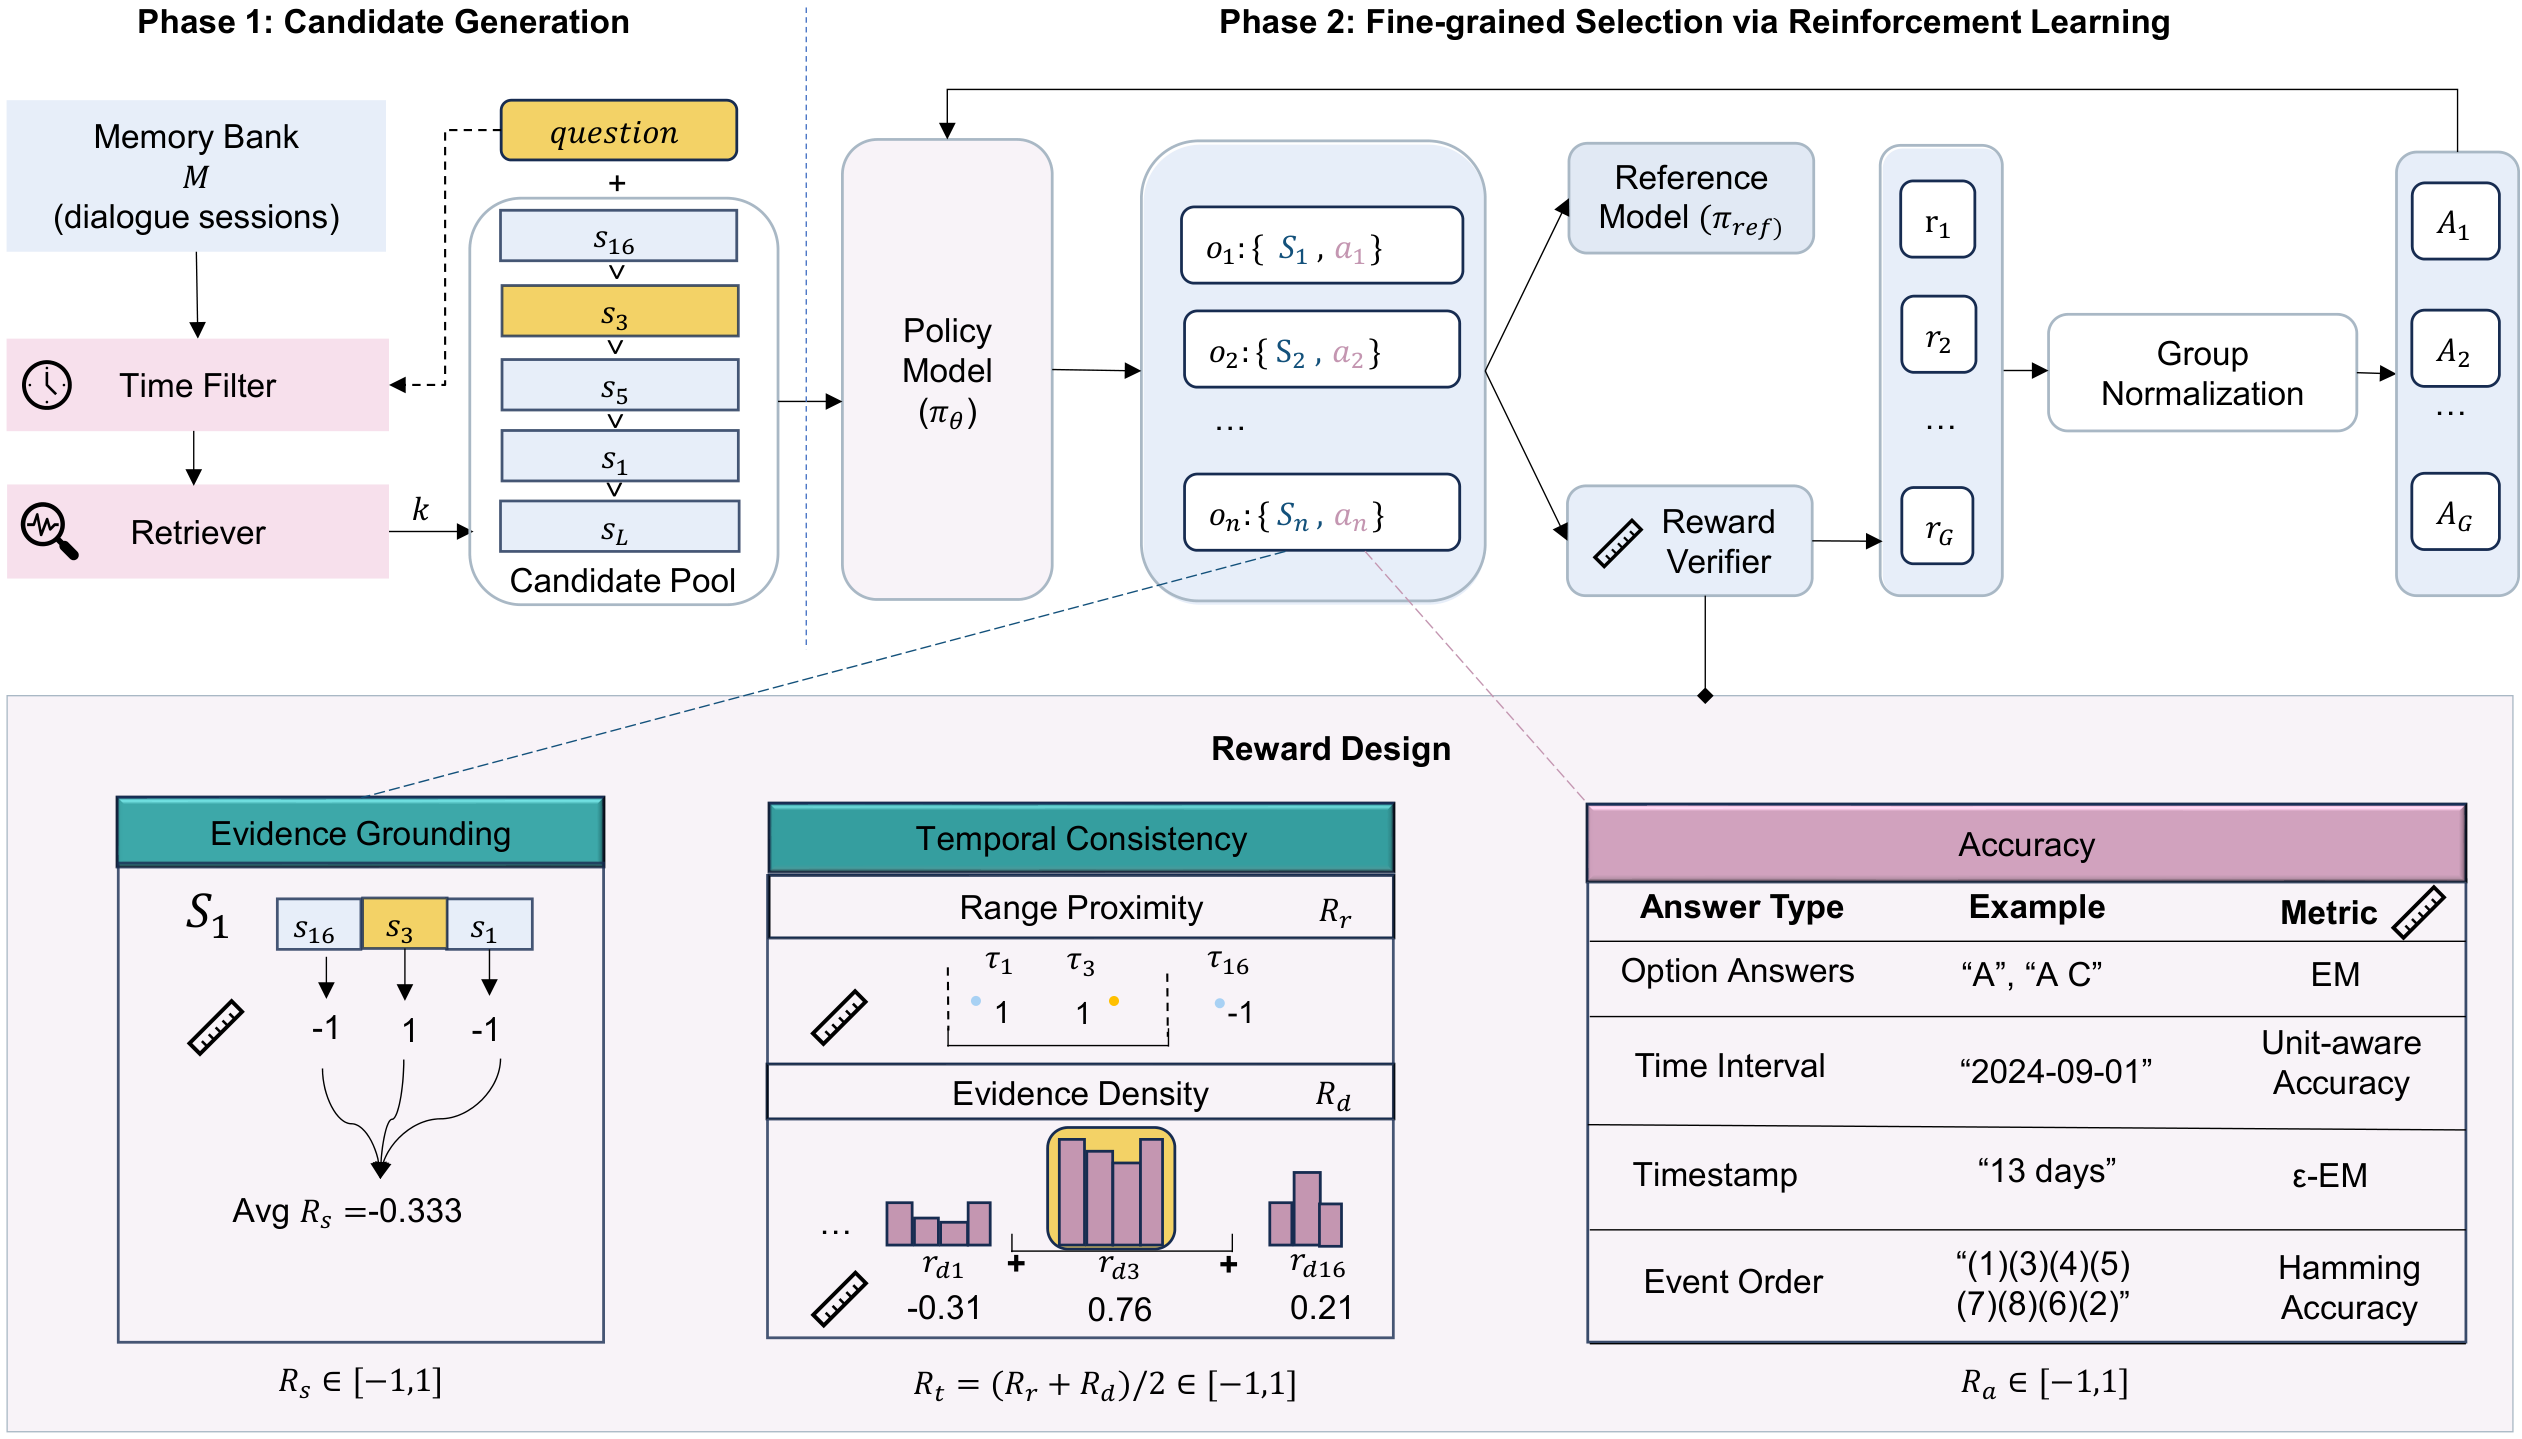 MEMORY-T1: Reinforcement Learning for Temporal Reasoning in Multi-Session AgentsIn International Conference on Learning Representations (ICLR), 2026
-
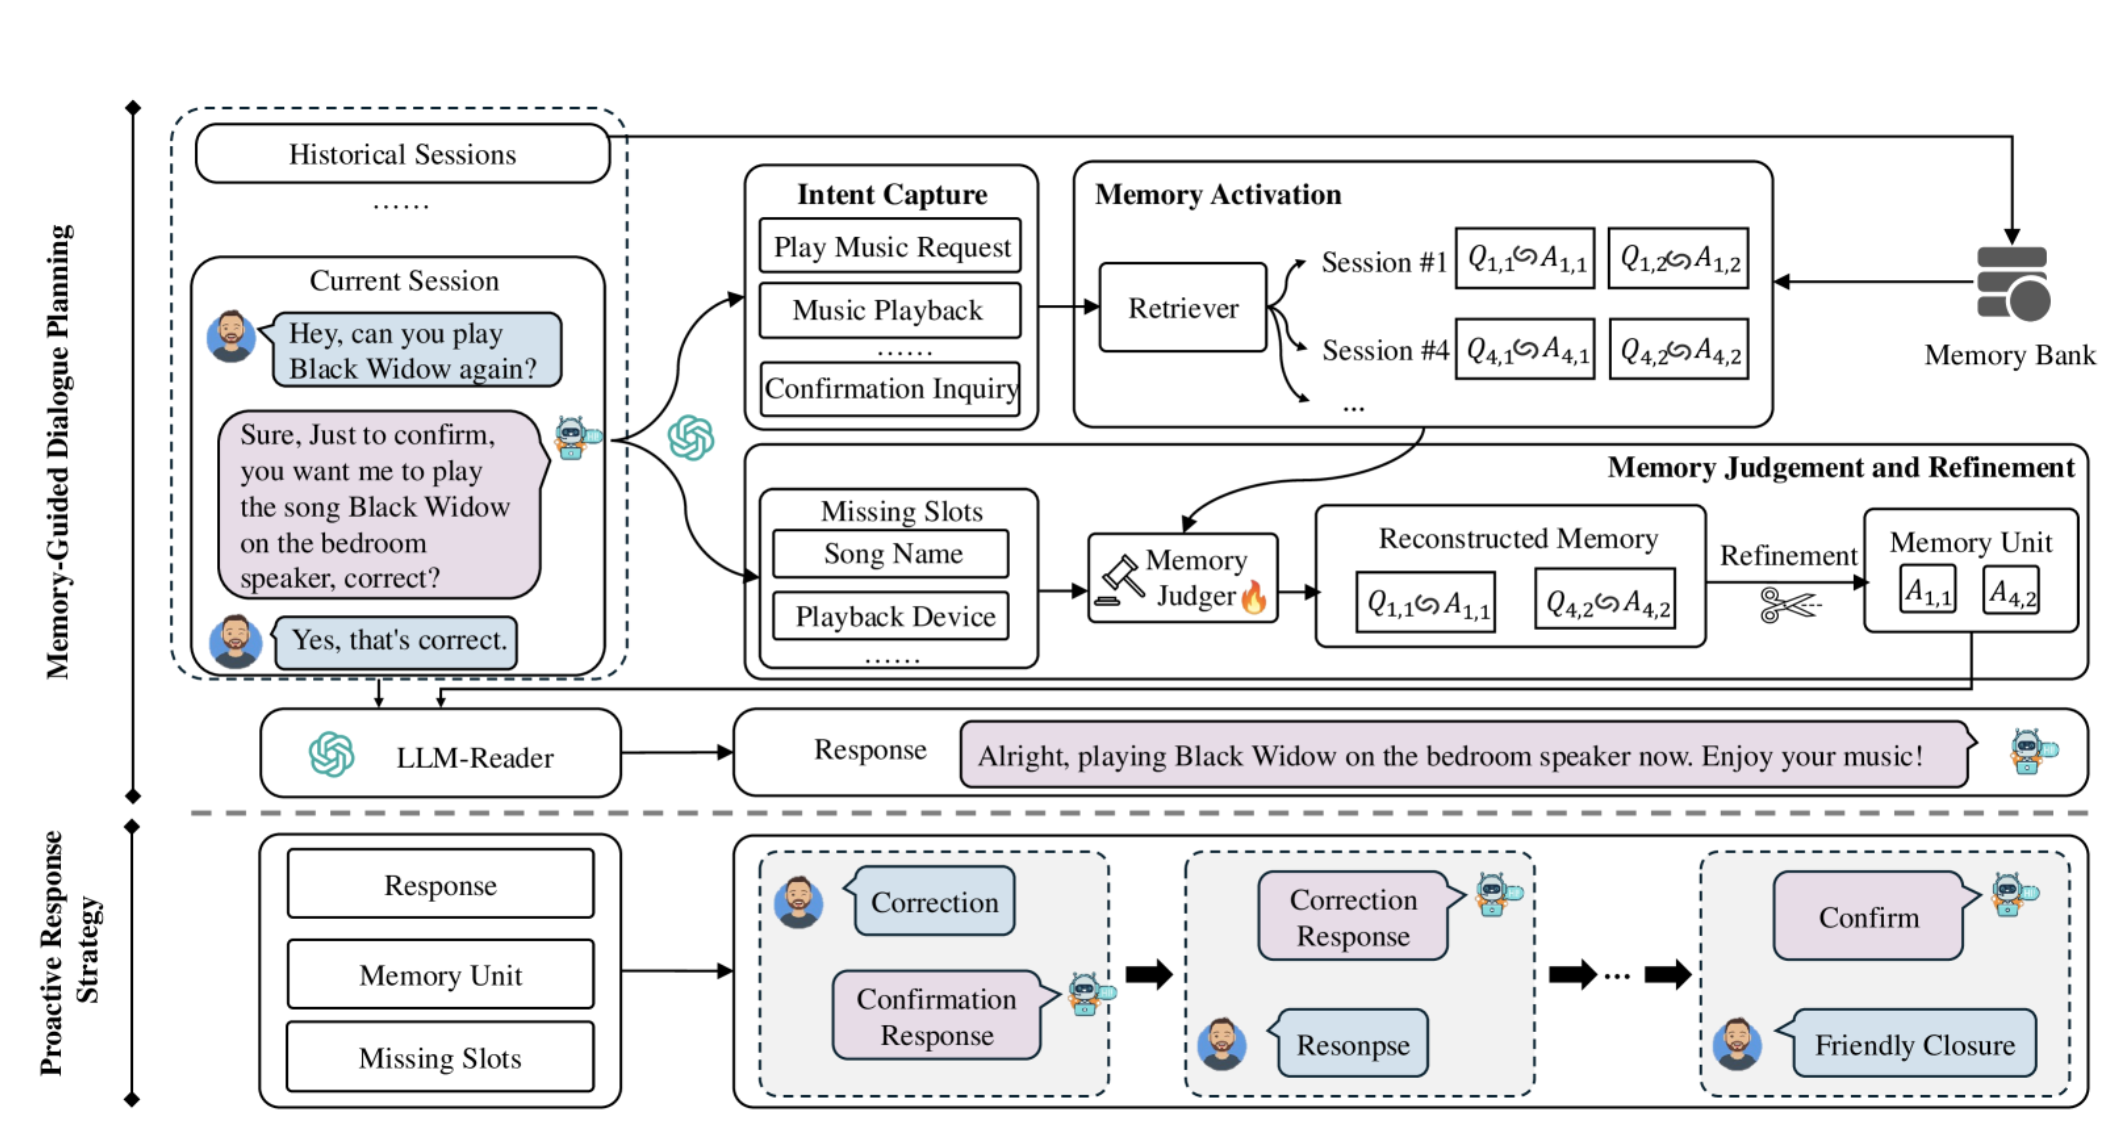 MemGuide: Intent-Driven Memory Selection for Goal-Oriented Multi-Session LLM AgentsIn Proceedings of the AAAI Conference on Artificial Intelligence, 2026Accepted, Oral. Co-first author with Bingbing Wang.
-
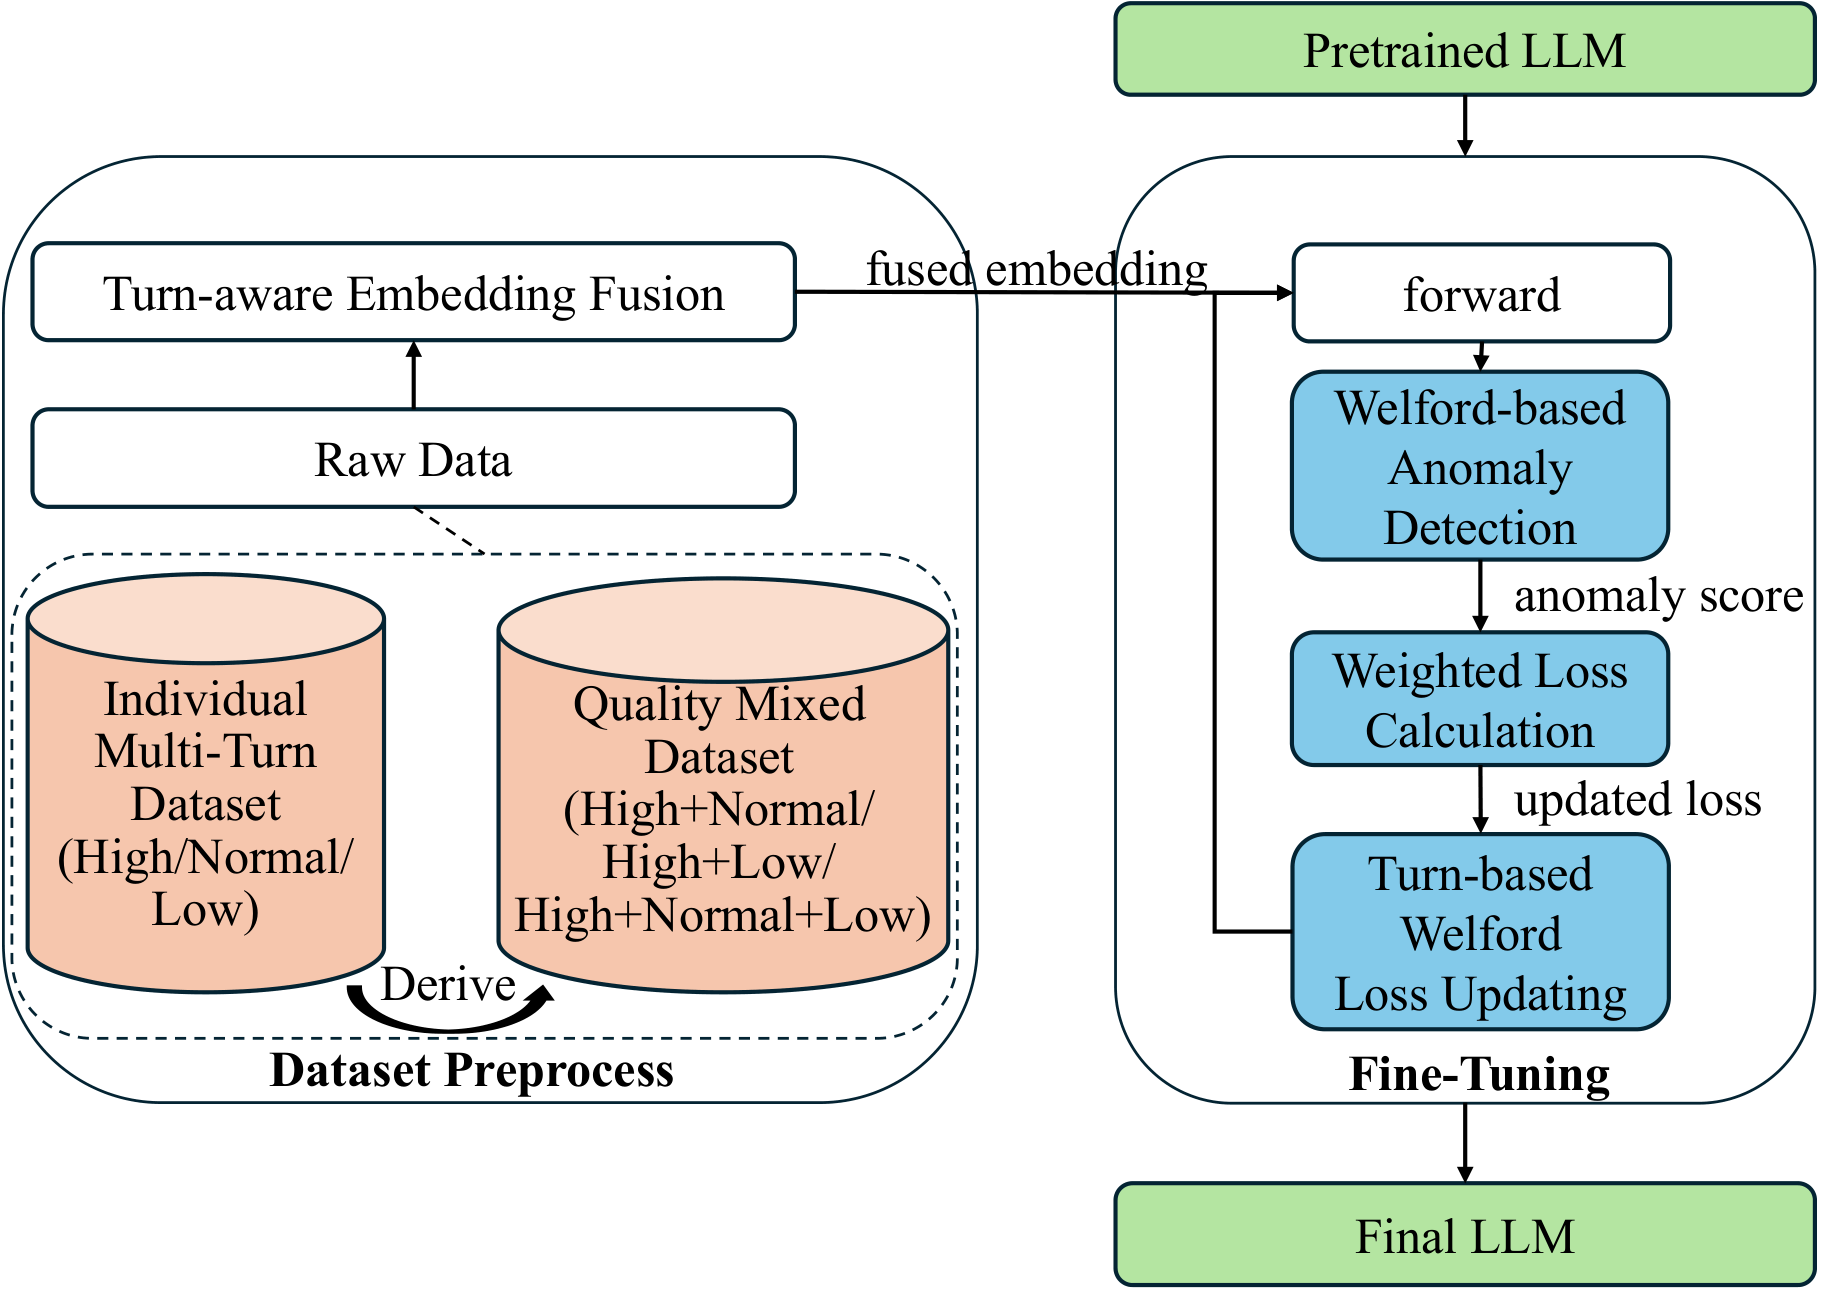 ReSURE: Regularizing Supervision Unreliability for Multi-turn Dialogue Fine-tuningIn Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing (EMNLP), 2025
-
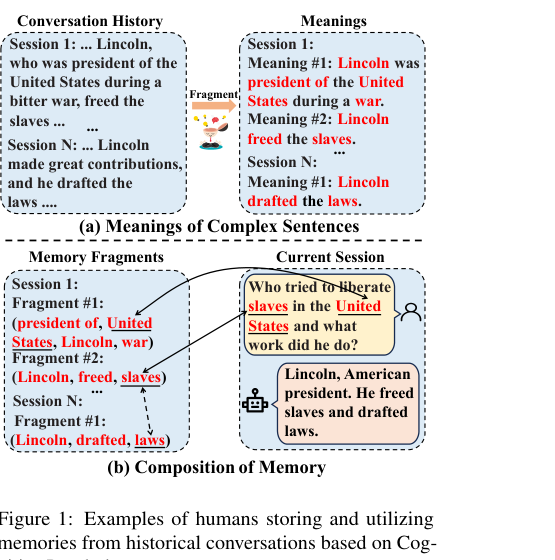 Flexibly Utilize Memory for Long-Term Conversation via a Fragment-then-Compose FrameworkIn Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing (EMNLP), 2025Accepted, Oral.
-
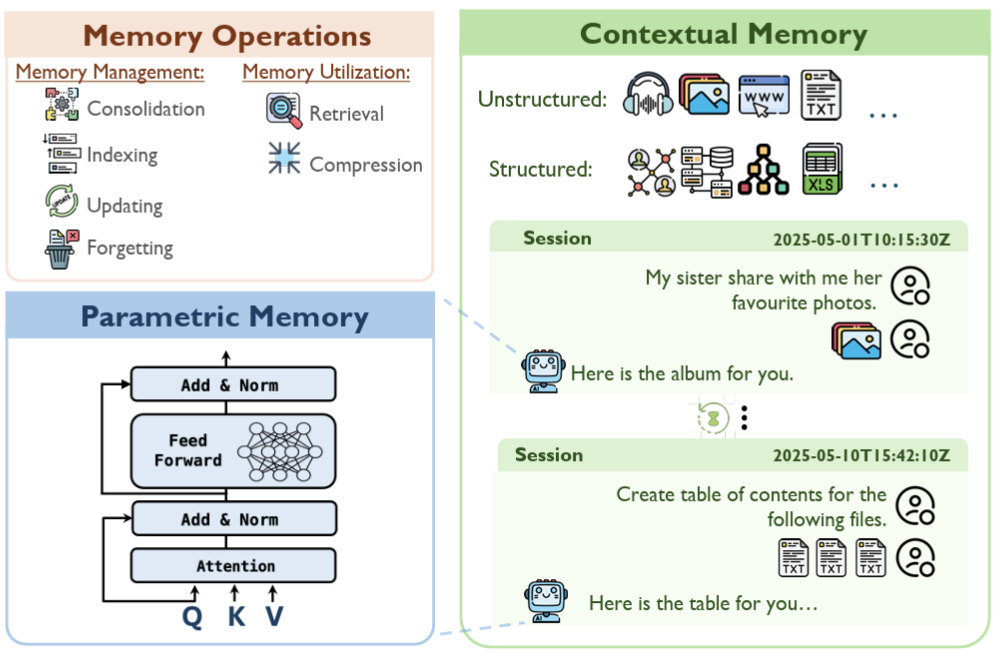 Rethinking Memory in AI: Taxonomy, Operations, Topics, and Future DirectionsarXiv preprint arXiv:2505.00675, 2025
-
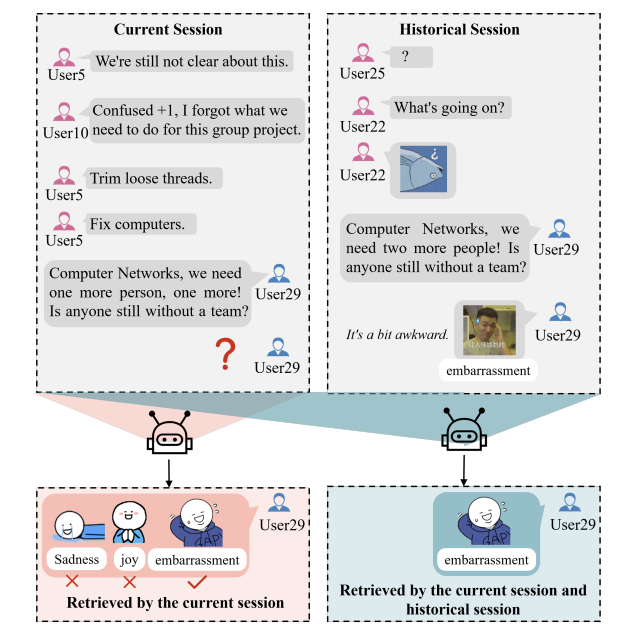 A New Formula for Sticker Retrieval: Reply with Stickers in Multi-Modal and Multi-Session ConversationIn Proceedings of the AAAI Conference on Artificial Intelligence, 2025Co-first author.
-
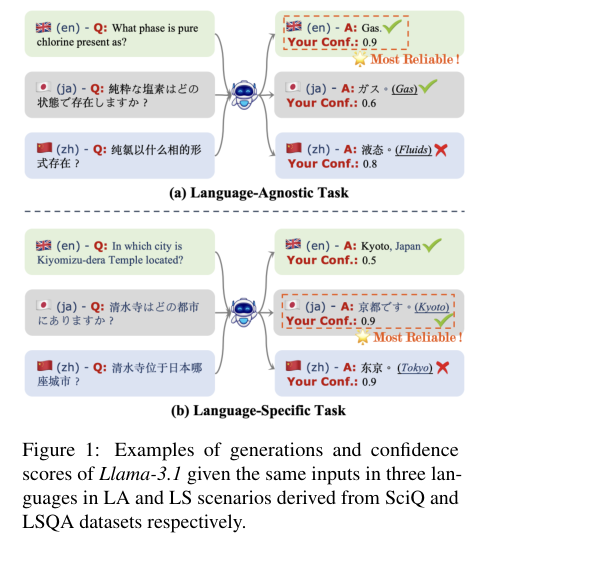 A Comprehensive Study of Multilingual Confidence Estimation on Large Language ModelsIn Findings of the Association for Computational Linguistics: ACL 2025, 2025
-
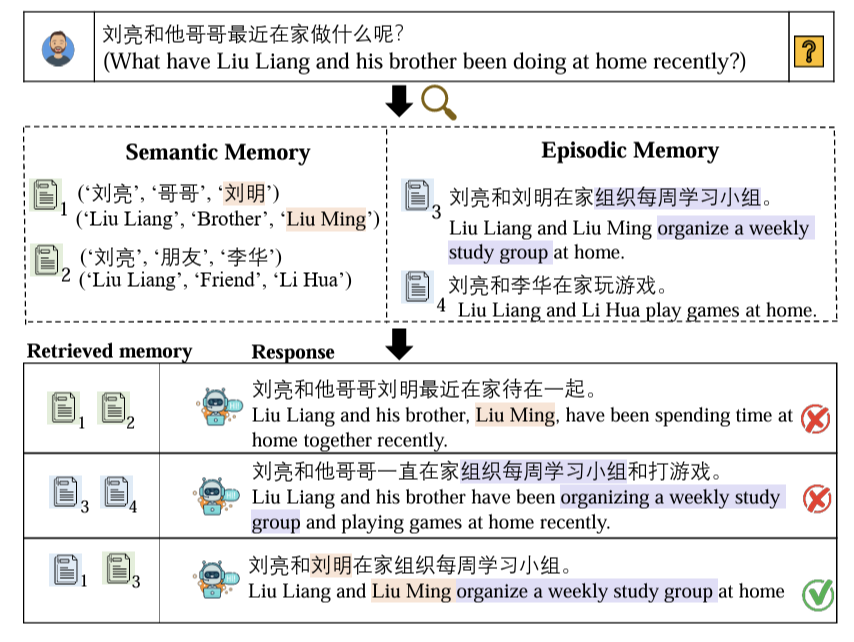 PerLTQA: A Personal Long-Term Memory Dataset for Memory Classification, Retrieval, and Fusion in Question AnsweringIn Proceedings of the 10th SIGHAN Workshop on Chinese Language Processing (SIGHAN-10), 2024Best Paper Award.